Learning and Interpreting Linear Regression
ECE 57000 — September 30, 2026
A new function class changes how we predict
Previously: KNN predicts from nearby stored examples.
Now: learn a shared function that combines the input coordinates.
We begin with house prices, then return to review sentiment.
First solve a model exactly; then learn how to optimize
| Stage | Question |
|---|---|
| 1. Regression → now | Which function, which loss, and what does the OLS solution mean? |
| 2. Classification | How do probabilities change the model and loss? |
| 3. Convexity | What makes these fitting problems well behaved? |
| 4. Optimization | How can local information guide numerical updates? |
| 5. Model limits | What can no linear fit express? |
Real Ames sales give us a numerical prediction task
Goal: predict a house’s sale price from its recorded characteristics.
- 2,930 real sales in Ames, Iowa, 2006–2010.
- Inputs include living area, construction year, bathrooms, and neighborhood.
- The target \(y\) is a dollar amount, rather than a class label.
This is regression: predict a numerical outcome.
A property becomes a vector of interpretable measurements
| Coordinate | Meaning | Example unit |
|---|---|---|
| Living area | Above-ground finished space | Square feet |
| Year built | Construction year | Calendar year |
| Garage capacity | Number of cars accommodated | Cars |
| Neighborhood indicator | Membership in one recorded neighborhood | 0 or 1 |
Indicator encoding: turn a category into 0/1 columns.
\[A\mapsto[1,0],\qquad B\mapsto[0,1],\qquad C\mapsto[0,0]\ \text{(reference)}.\]
75 property fields → 226 numerical coordinates after encoding.
KNN can predict a number by averaging nearby outcomes
For the \(k\) nearest training inputs, indexed by \(N_k(\boldsymbol{x})\):
\[\widehat f_{\mathcal D}(\boldsymbol{x})=\frac1k\sum_{i\in N_k(\boldsymbol{x})}y_i.\]
Three neighboring sales: $150,000, $180,000, and $210,000 → $180,000.
The lookup mechanism is familiar; averaging replaces the classification vote.
The same sales support a local rule or a single fitted line
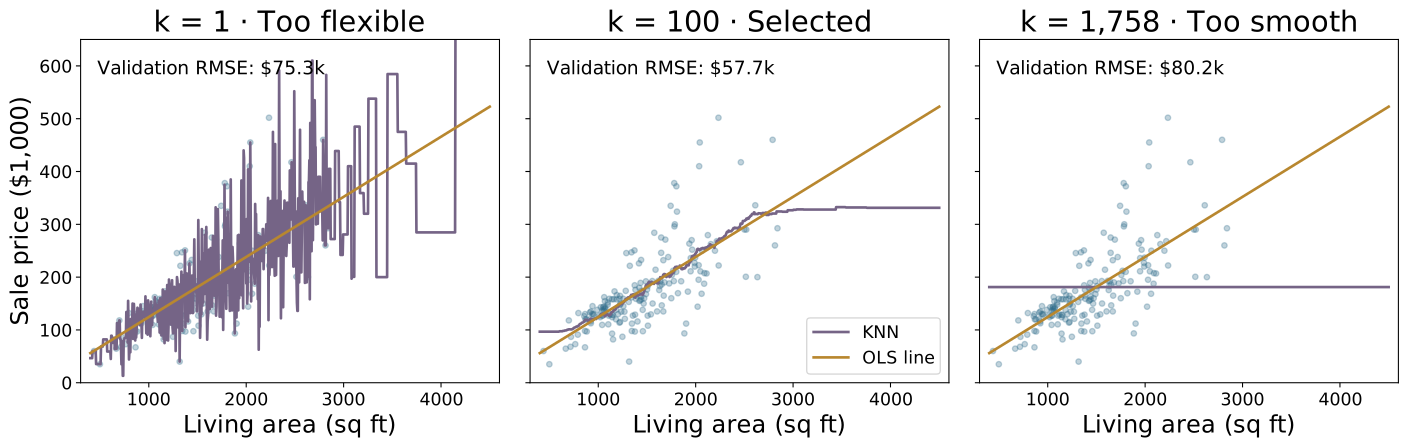
Same training sales and living area alone: small \(k\) follows local fluctuations; very large \(k\) loses the trend.
\(k=100\) is within 0.3% of the best validation RMSE across all \(k\).
A parametric model learns shared coefficients
| KNN regression | Linear regression |
|---|---|
| Retain examples; find neighbors for each query. | Fit coefficients; reuse the same formula for every query. |
| The stored model grows with the dataset. | For fixed features, the number of coefficients stays fixed. |
| Nonparametric | Parametric |
These names describe model structure, not whether a method has settings such as \(k\).
A line predicts with a slope and an offset
\[\widehat y=f_{w,b}(x)=wx+b.\]
- \(x\): measured living area; \(\widehat y\): predicted price.
- \(w\): change in prediction per additional square foot.
- \(b\): where the fitted line meets the vertical axis.
For the one-input Ames fit: 100 more sq ft → about $11,400 more predicted price.
More inputs give a weighted sum of contributions
\[\widehat y=\boldsymbol{w}^{\mathsf T}\boldsymbol{x}+b =\sum_{j=1}^d w_jx_j+b.\]
A coefficient \(w_j\) changes the prediction per unit of \(x_j\), holding the other coordinates fixed.
With 226 input coordinates, there are 227 coefficients including the offset.
The conventional name is “linear model”; the offset makes this formally affine.
Fitted coefficients determine differences in predicted price
Rounded coefficients from the four-feature Ames model:
| Feature | Coefficient per unit |
|---|---|
| Living area (sq ft) | +$90 |
| Construction year | +$840 |
| Full bathrooms | −$11,500 |
| Garage spaces | +$23,600 |
Compare two houses: same year and bathrooms; house B has 100 more sq ft and one fewer garage space.
\[\widehat y_B-\widehat y_A\approx 100(90)-23{,}600=-\$14{,}600.\]
Choosing a function leaves which coefficients? unresolved
Established: every \((\boldsymbol{w},b)\) gives a prediction rule.
Next: quantify fitting error, solve for coefficients, and interpret the solution.
Our KNN procedure had no explicit training-objective minimization. Here we will explicitly minimize squared prediction error.
Residuals measure vertical prediction errors
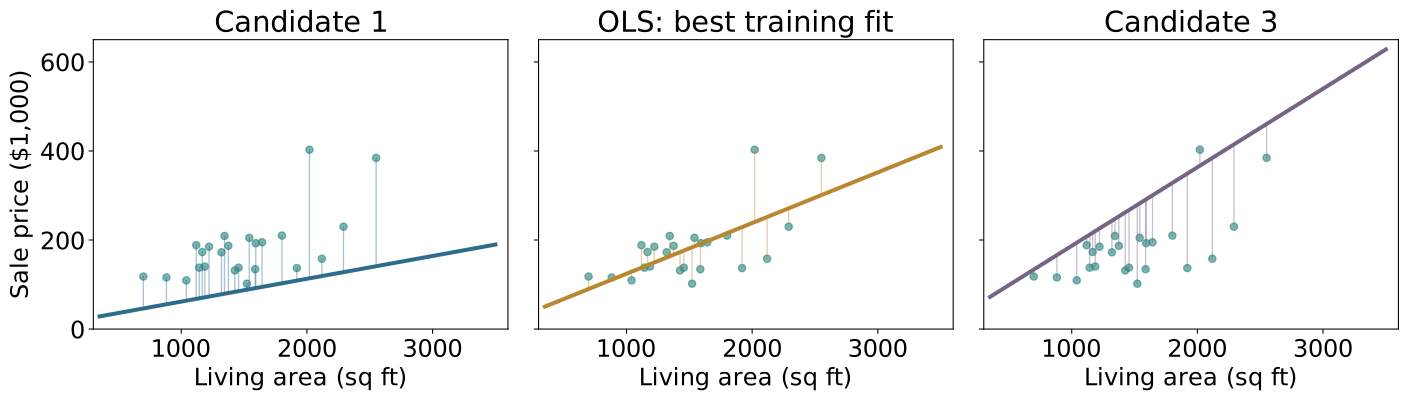
\(r_i=y_i-\widehat y_i\): observed price minus predicted price.
Mean squared error makes large residuals costly
\[\operatorname{MSE}=\frac1n\sum_{i=1}^n(\widehat y_i-y_i)^2, \qquad J(\boldsymbol{w},b)=\frac12\operatorname{MSE}.\]
Doubling a residual multiplies its squared contribution by four.
The factor \(1/2\) simplifies derivatives; it does not change the minimizer.
For interpretation: \(\operatorname{RMSE}=\sqrt{\operatorname{MSE}}\) is a standard-deviation-like error scale in dollars, rather than dollars squared.
For fitting: minimize squared error; taking the square root adds no new minimizer and complicates the derivatives.
Can large positive and negative errors cancel the fitting problem?
A model makes two residuals: +$50,000 and −$50,000.
What does their zero average establish?
A. The model has zero mean squared error.
B. The signs balance, but squared error can still be large.
C. The fitted line must be the least-squares solution.
B. Squaring prevents opposite signs from hiding large mistakes.
First solve one input and one fitted line
Simplify to build intuition: living area \(x\) predicts price \(y\) using \(wx+b\).
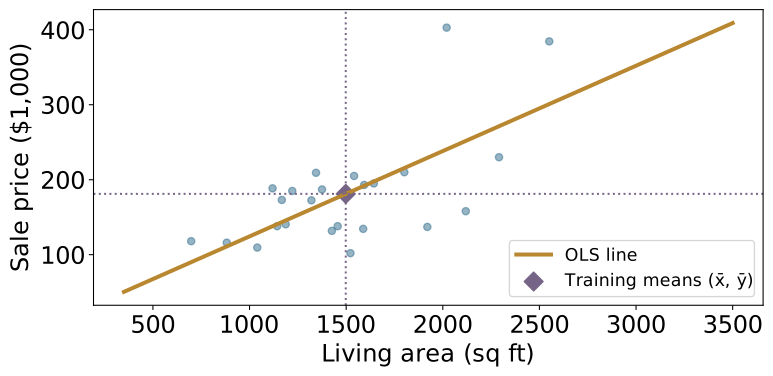
At \(x=\bar x\), choosing \(b=\bar y-w\bar x\) gives \(w\bar x+b=w\bar x+(\bar y-w\bar x)=\bar y\).
This places the line through \((\bar x,\bar y)\). Why is that offset optimal?
Optimizing the offset balances the residuals
\(J(w,b)=\frac1{2n}\sum_i(wx_i+b-y_i)^2\).
\(\displaystyle \frac{\partial J}{\partial b}\)
\(=\)
\(\displaystyle \frac1n\sum_i(wx_i+b-y_i)\)
(Differentiate each squared residual)
\(\displaystyle \,\)
\(=\)
\(\displaystyle w\frac1n\sum_i x_i+b-\frac1n\sum_i y_i\)
(Distribute the sum; b repeats n times)
\(\displaystyle 0\)
\(=\)
\(\displaystyle w\bar x+b-\bar y\)
(Set the derivative to zero)
\(\displaystyle \widehat b(w)\)
\(=\)
\(\displaystyle \bar y-w\bar x\)
(Solve for b at a fixed slope)
The intercept derivative is the mean prediction error: this choice makes it zero.
Substituting the offset centers both inputs and outcomes
Write \(x_i^c=x_i-\bar x\) and \(y_i^c=y_i-\bar y\).
\(\displaystyle wx_i+\widehat b(w)-y_i\)
\(=\)
\(\displaystyle wx_i+(\bar y-w\bar x)-y_i\)
(Substitute the optimal offset)
\(\displaystyle \,\)
\(=\)
\(\displaystyle w(x_i-\bar x)-(y_i-\bar y)=wx_i^c-y_i^c\)
(Collect centered quantities)
\(\displaystyle \frac{d}{dw}J(w,\widehat b(w))\)
\(=\)
\(\displaystyle \frac1n\sum_i x_i^c(wx_i^c-y_i^c)\)
(Differentiate the centered squared errors)
Now set this derivative to zero and solve for the slope.
Rearranging the zero derivative gives the closed-form slope
\(\displaystyle 0\)
\(=\)
\(\displaystyle \sum_i x_i^c(\widehat w x_i^c-y_i^c)\)
(Set derivative to zero; multiply by n)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \sum_i\left[\widehat w(x_i^c)^2-x_i^cy_i^c\right]\)
(Distribute each product)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \widehat w\sum_i(x_i^c)^2-\sum_i x_i^cy_i^c\)
(Take the shared slope outside the sum)
\(\displaystyle \widehat w\sum_i(x_i^c)^2\)
\(=\)
\(\displaystyle \sum_i x_i^cy_i^c\)
(Move the cross-products to the other side)
\(\displaystyle \widehat w\)
\(=\)
\(\displaystyle \frac{\sum_i x_i^cy_i^c}{\sum_i(x_i^c)^2}\)
(Divide by the input sum of squares)
Each observation contributes a signed product and a squared distance
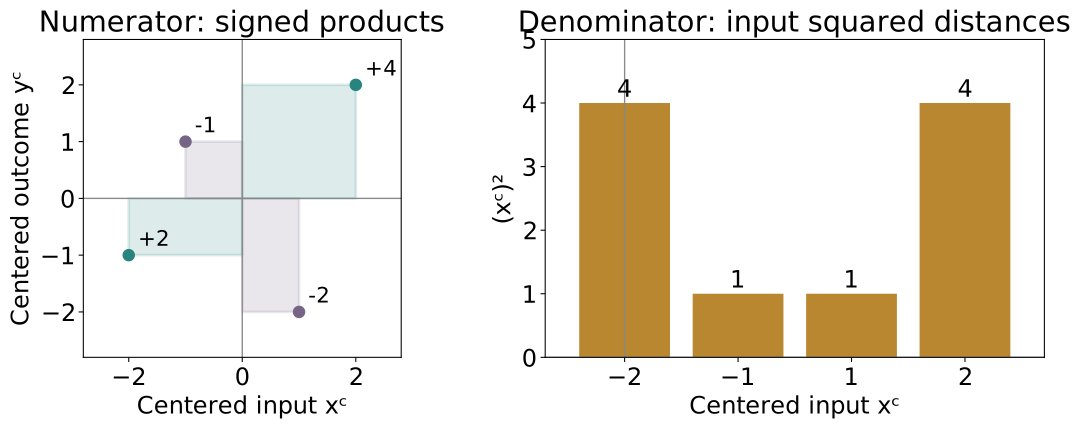
Toy centered data: numerator \(=2-1-2+4=3\); denominator \(=4+1+1+4=10\).
Same-sign deviations support a positive slope; opposite signs oppose it. Here \(\widehat w=3/10\).
The fitted slope is a weighted average of slopes from the mean
For observations with \(x_i^c\ne0\):
\[\widehat w=\sum_i\underbrace{\frac{(x_i^c)^2}{\sum_j(x_j^c)^2}}_{\text{weight, summing to 1}} \underbrace{\frac{y_i^c}{x_i^c}}_{\text{slope from the mean point}}.\]
Inputs farther from the mean have more weight in determining the slope.
Dividing by \(\sum_i(x_i^c)^2\) normalizes the weights. It is not an unweighted average of the individual slopes.
Finally, \(\widehat b=\bar y-\widehat w\bar x\) positions this slope through the mean point.
Stacking predictions turns the problem into one matrix equation
Put observations in rows of \(X\in\mathbb R^{n\times d}\).
\[\widetilde X=[X\;\boldsymbol{1}],\qquad \boldsymbol{\theta}=\begin{bmatrix}\boldsymbol{w}\\b\end{bmatrix}, \qquad \widehat{\boldsymbol{y}}=\widetilde X\boldsymbol{\theta}.\]
\[J(\boldsymbol{\theta})=\frac1{2n}\|\widetilde X\boldsymbol{\theta}-\boldsymbol{y}\|_2^2.\]
Shape check: \((n\times(d+1))((d+1)\times1)=n\times1\) predictions.
Write squared error as an inner product before expanding
\(\displaystyle J(\boldsymbol{\theta})\)
\(=\)
\(\displaystyle \frac1{2n}\|\widetilde X\boldsymbol{\theta}-\boldsymbol{y}\|_2^2\)
(Squared-residual form)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \frac1{2n}(\widetilde X\boldsymbol{\theta}-\boldsymbol{y})^{\mathsf T}(\widetilde X\boldsymbol{\theta}-\boldsymbol{y})\)
(A squared norm is an inner product)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \frac1{2n}(\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}-\boldsymbol{y}^{\mathsf T})(\widetilde X\boldsymbol{\theta}-\boldsymbol{y})\)
(Transpose the difference)
The expansion contains two equal scalar cross terms
\(\displaystyle 2nJ(\boldsymbol{\theta})\)
\(=\)
\(\displaystyle \begin{aligned}[t]&\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}-\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\boldsymbol{y}\\&{}-\boldsymbol{y}^{\mathsf T}\widetilde X\boldsymbol{\theta}+\boldsymbol{y}^{\mathsf T}\boldsymbol{y}\end{aligned}\)
(Multiply out all four terms)
\(\displaystyle \boldsymbol{y}^{\mathsf T}\widetilde X\boldsymbol{\theta}\)
\(=\)
\(\displaystyle (\boldsymbol{y}^{\mathsf T}\widetilde X\boldsymbol{\theta})^{\mathsf T}=\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\boldsymbol{y}\)
(A scalar equals its transpose)
\(\displaystyle 2nJ(\boldsymbol{\theta})\)
\(=\)
\(\displaystyle \boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}-2\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\boldsymbol{y}+\boldsymbol{y}^{\mathsf T}\boldsymbol{y}\)
(Combine the cross terms)
Differentiate each term, then set the gradient to zero
The matrix \(\widetilde X^{\mathsf T}\widetilde X\) is symmetric.
| Term in \(2nJ\) | Gradient with respect to \(\boldsymbol{\theta}\) |
|---|---|
| \(\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}\) | \(2\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}\) |
| \(-2\boldsymbol{\theta}^{\mathsf T}\widetilde X^{\mathsf T}\boldsymbol{y}\) | \(-2\widetilde X^{\mathsf T}\boldsymbol{y}\) |
| \(\boldsymbol{y}^{\mathsf T}\boldsymbol{y}\) | \(\boldsymbol{0}\): independent of the coefficients |
\(\displaystyle \nabla J(\boldsymbol{\theta})\)
\(=\)
\(\displaystyle \frac1{2n}(2\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}-2\widetilde X^{\mathsf T}\boldsymbol{y}+\boldsymbol{0})\)
(Combine the term derivatives)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \frac1n(\widetilde X^{\mathsf T}\widetilde X\boldsymbol{\theta}-\widetilde X^{\mathsf T}\boldsymbol{y})\)
(Cancel the factor of two)
\(\displaystyle \boldsymbol{0}\)
\(=\)
\(\displaystyle \frac1n(\widetilde X^{\mathsf T}\widetilde X\widehat{\boldsymbol{\theta}}-\widetilde X^{\mathsf T}\boldsymbol{y})\)
(Set the gradient to zero)
\(\displaystyle \widetilde X^{\mathsf T}\widetilde X\widehat{\boldsymbol{\theta}}\)
\(=\)
\(\displaystyle \widetilde X^{\mathsf T}\boldsymbol{y}\)
(Multiply by n; rearrange)
Independent columns give the OLS inverse formula
If \(\widetilde X\) has full column rank:
\[\boxed{\widehat{\boldsymbol{\theta}}= (\widetilde X^{\mathsf T}\widetilde X)^{-1}\widetilde X^{\mathsf T}\boldsymbol{y}.}\]
- \(\widetilde X^{\mathsf T}\boldsymbol{y}\) measures feature–outcome alignment.
- \(\widetilde X^{\mathsf T}\widetilde X\) records feature sizes and overlap.
- Its inverse accounts for that overlap when assigning coefficients.
In code, use a least-squares solver, rather than explicitly forming the inverse.
At the solution, residuals are orthogonal to every feature
Let \(\boldsymbol{r}=\boldsymbol{y}-\widetilde X\widehat{\boldsymbol{\theta}}\).
\(\displaystyle \widetilde X^{\mathsf T}\boldsymbol{r}\)
\(=\)
\(\displaystyle \widetilde X^{\mathsf T}(\boldsymbol{y}-\widetilde X\widehat{\boldsymbol{\theta}})\)
(Substitute the residual vector)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \widetilde X^{\mathsf T}\boldsymbol{y}-\widetilde X^{\mathsf T}\widetilde X\widehat{\boldsymbol{\theta}}\)
(Distribute the matrix product)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \boldsymbol{0}\)
(Use the normal equations)
Each feature column has zero dot product with the residual vector: no residual component lies along a direction the model can adjust.
The column of ones also gives \(\sum_i r_i=0\): overpredictions and underpredictions balance.
Orthogonality proves that no other fit has lower error
Any other coefficient vector is \(\widehat{\boldsymbol{\theta}}+\boldsymbol{\delta}\).
\(\displaystyle \|\boldsymbol{y}-\widetilde X(\widehat{\boldsymbol{\theta}}+\boldsymbol{\delta})\|^2\)
\(=\)
\(\displaystyle \|\boldsymbol{r}-\widetilde X\boldsymbol{\delta}\|^2\)
(Write the new residual)
\(\displaystyle \,\)
\(=\)
\(\displaystyle \|\boldsymbol{r}\|^2+\|\widetilde X\boldsymbol{\delta}\|^2\)
(Cross term vanishes: residual orthogonality)
\(\displaystyle \,\)
\(\ge\)
\(\displaystyle \|\boldsymbol{r}\|^2\)
(A squared norm is nonnegative)
The bound is attained: choose \(\boldsymbol{\delta}=\boldsymbol{0}\), so \(\|\widetilde X\boldsymbol{\delta}\|^2=0\).
Thus \(\widehat{\boldsymbol{\theta}}\) achieves the smallest possible squared error, \(\|\boldsymbol{r}\|^2\): it is a global minimum.